

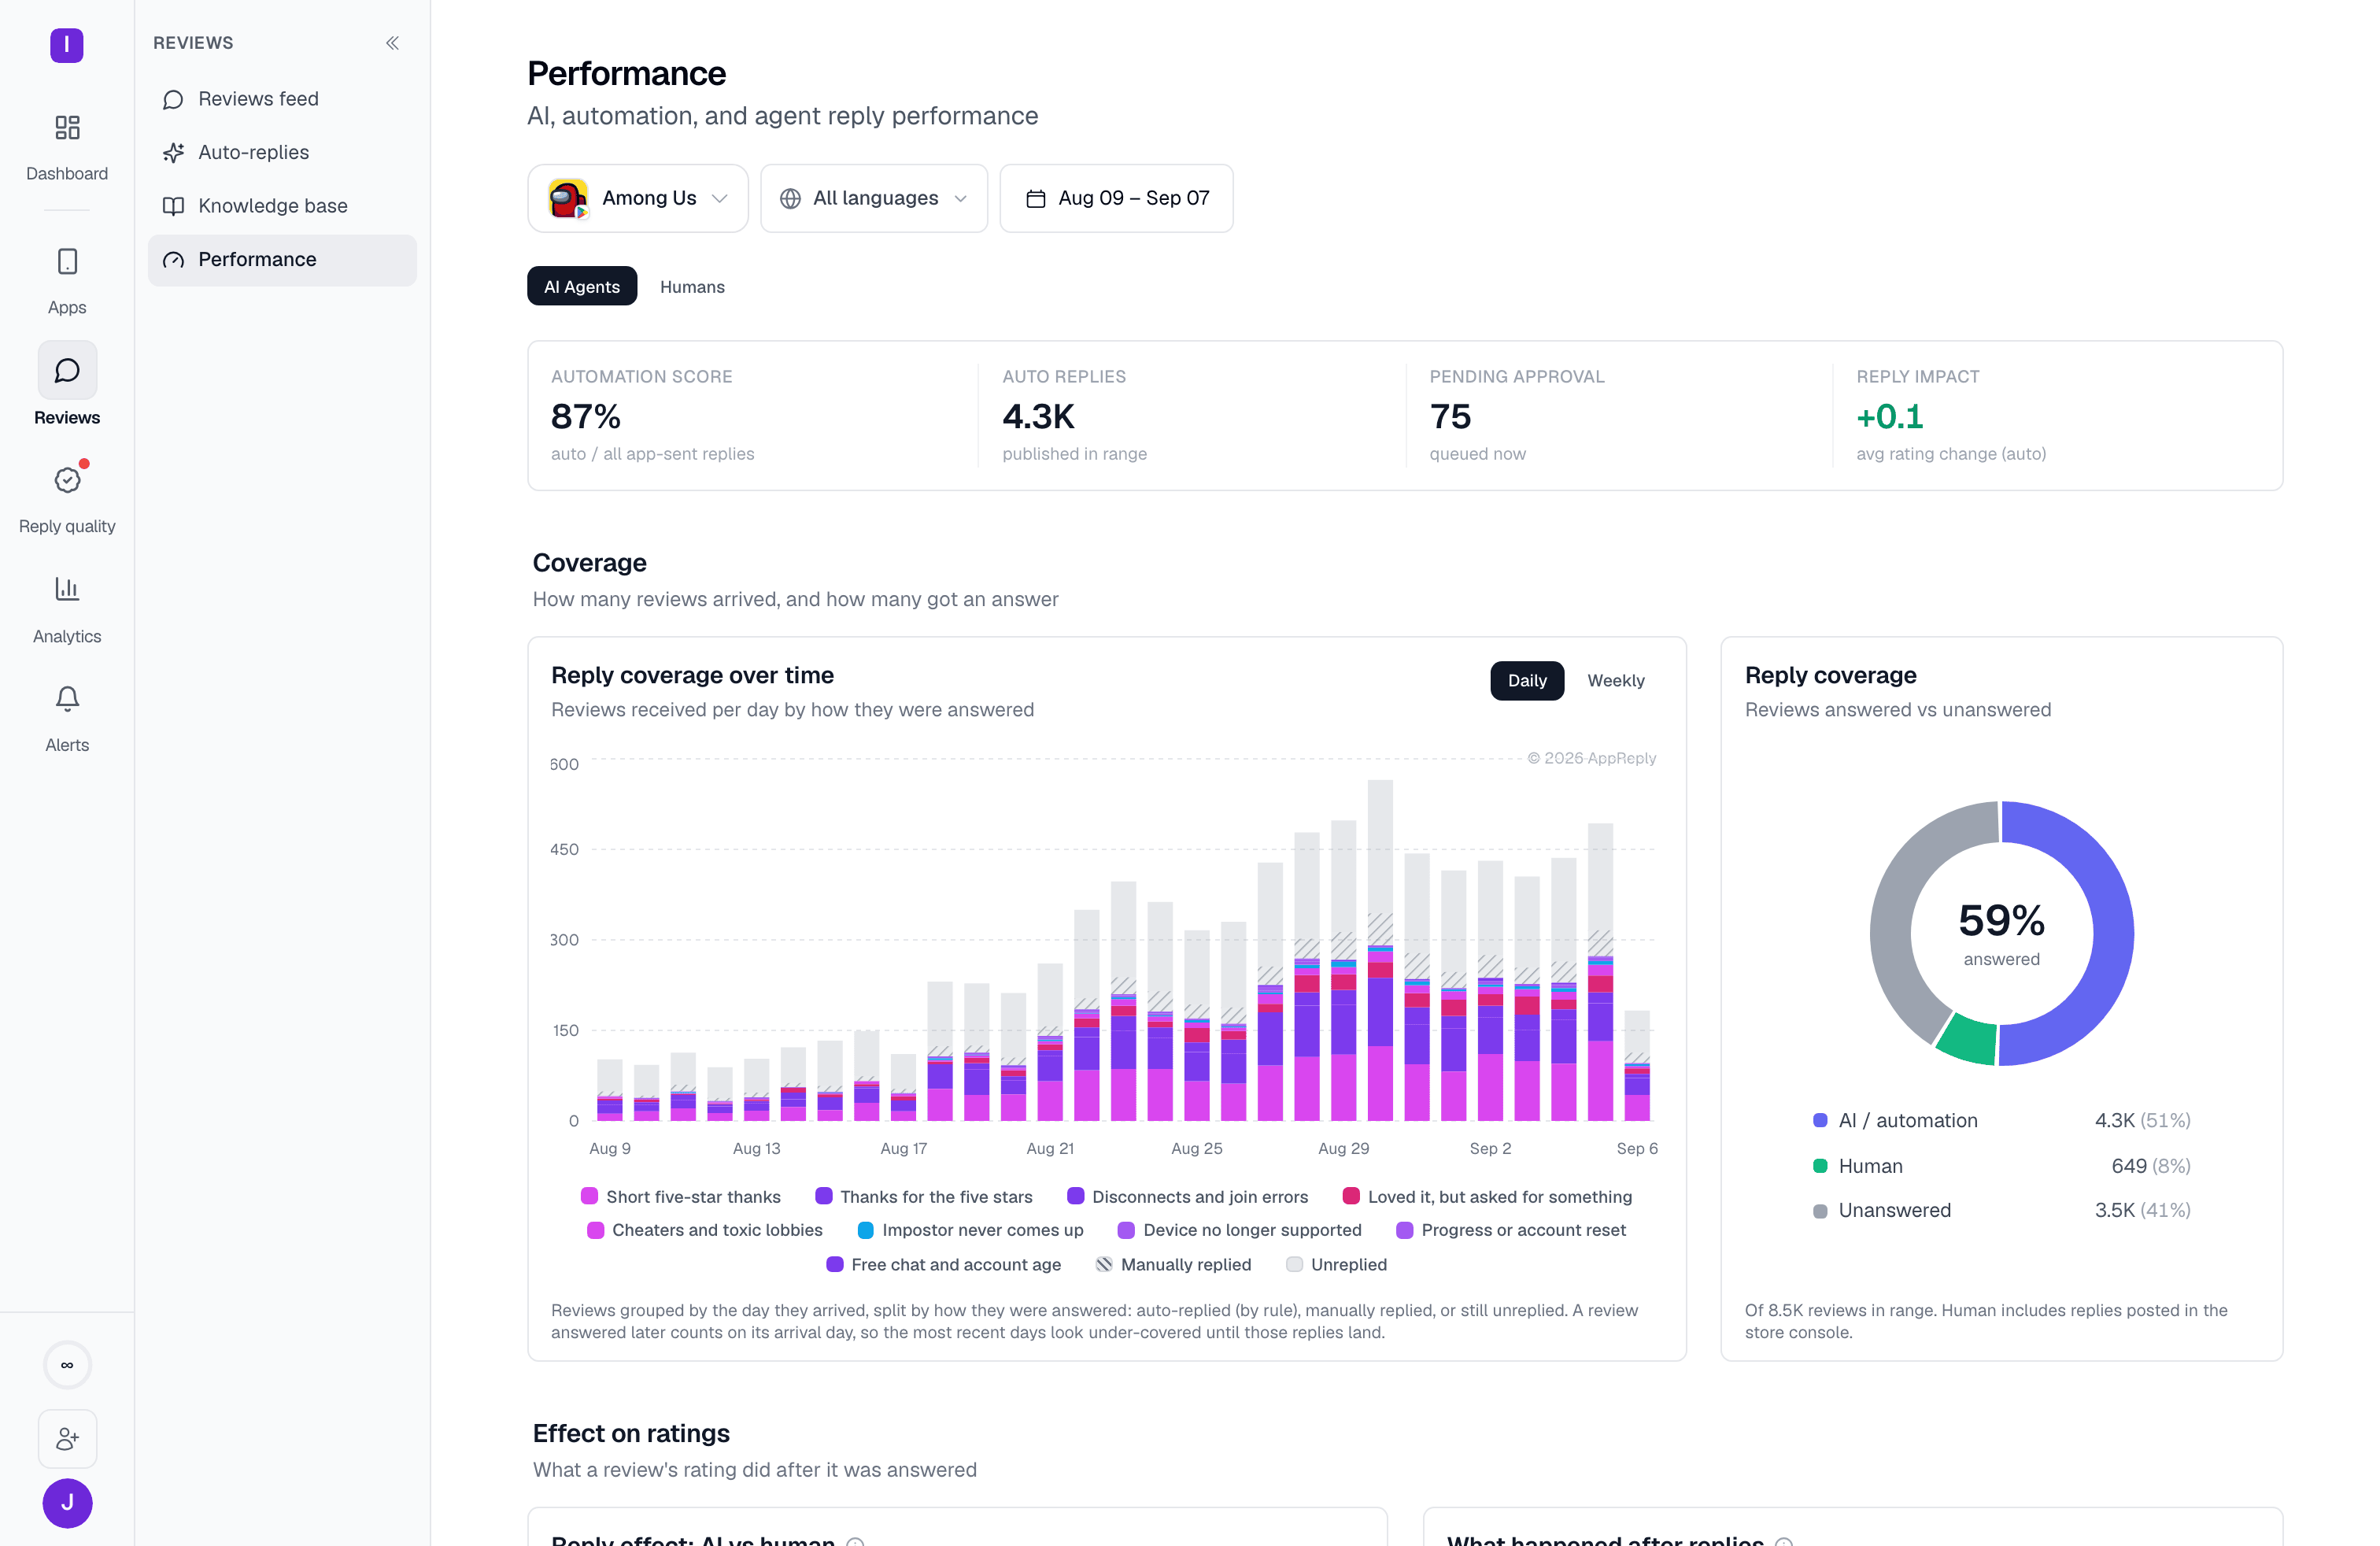
Both tabs require a Pro or Ultimate plan (or an active trial); other orgs see an upgrade prompt in place of the charts. The Humans tab is additionally visible to Admins and Owners only — Members see just the AI Agents tab, with no second tab shown.
AI Agents tab
This tab opens with a summary strip of four numbers:- Automation score — the share of your app-sent replies that were automated
- Auto replies — replies posted in the window
- Pending approval — replies queued now
- Reply impact — the rating effect of automated replies
Coverage
A time-series chart tracks daily reply coverage: how many reviews arrived, and how many got an answer. Next to it, a reply coverage donut shows the same split (answered vs. unanswered) for the window. The time series can be viewed aggregated by day or rolled up weekly, which smooths day-to-day noise on a longer window. For a window of 28 days or more, the chart opens on weekly. Your own Daily or Weekly choice sticks until you pick a window with a different default. The chart’s legend lists the ten busiest rules, then a +N more rules toggle (Show fewer collapses it again). The cap never hides the Manually replied and Unreplied keys.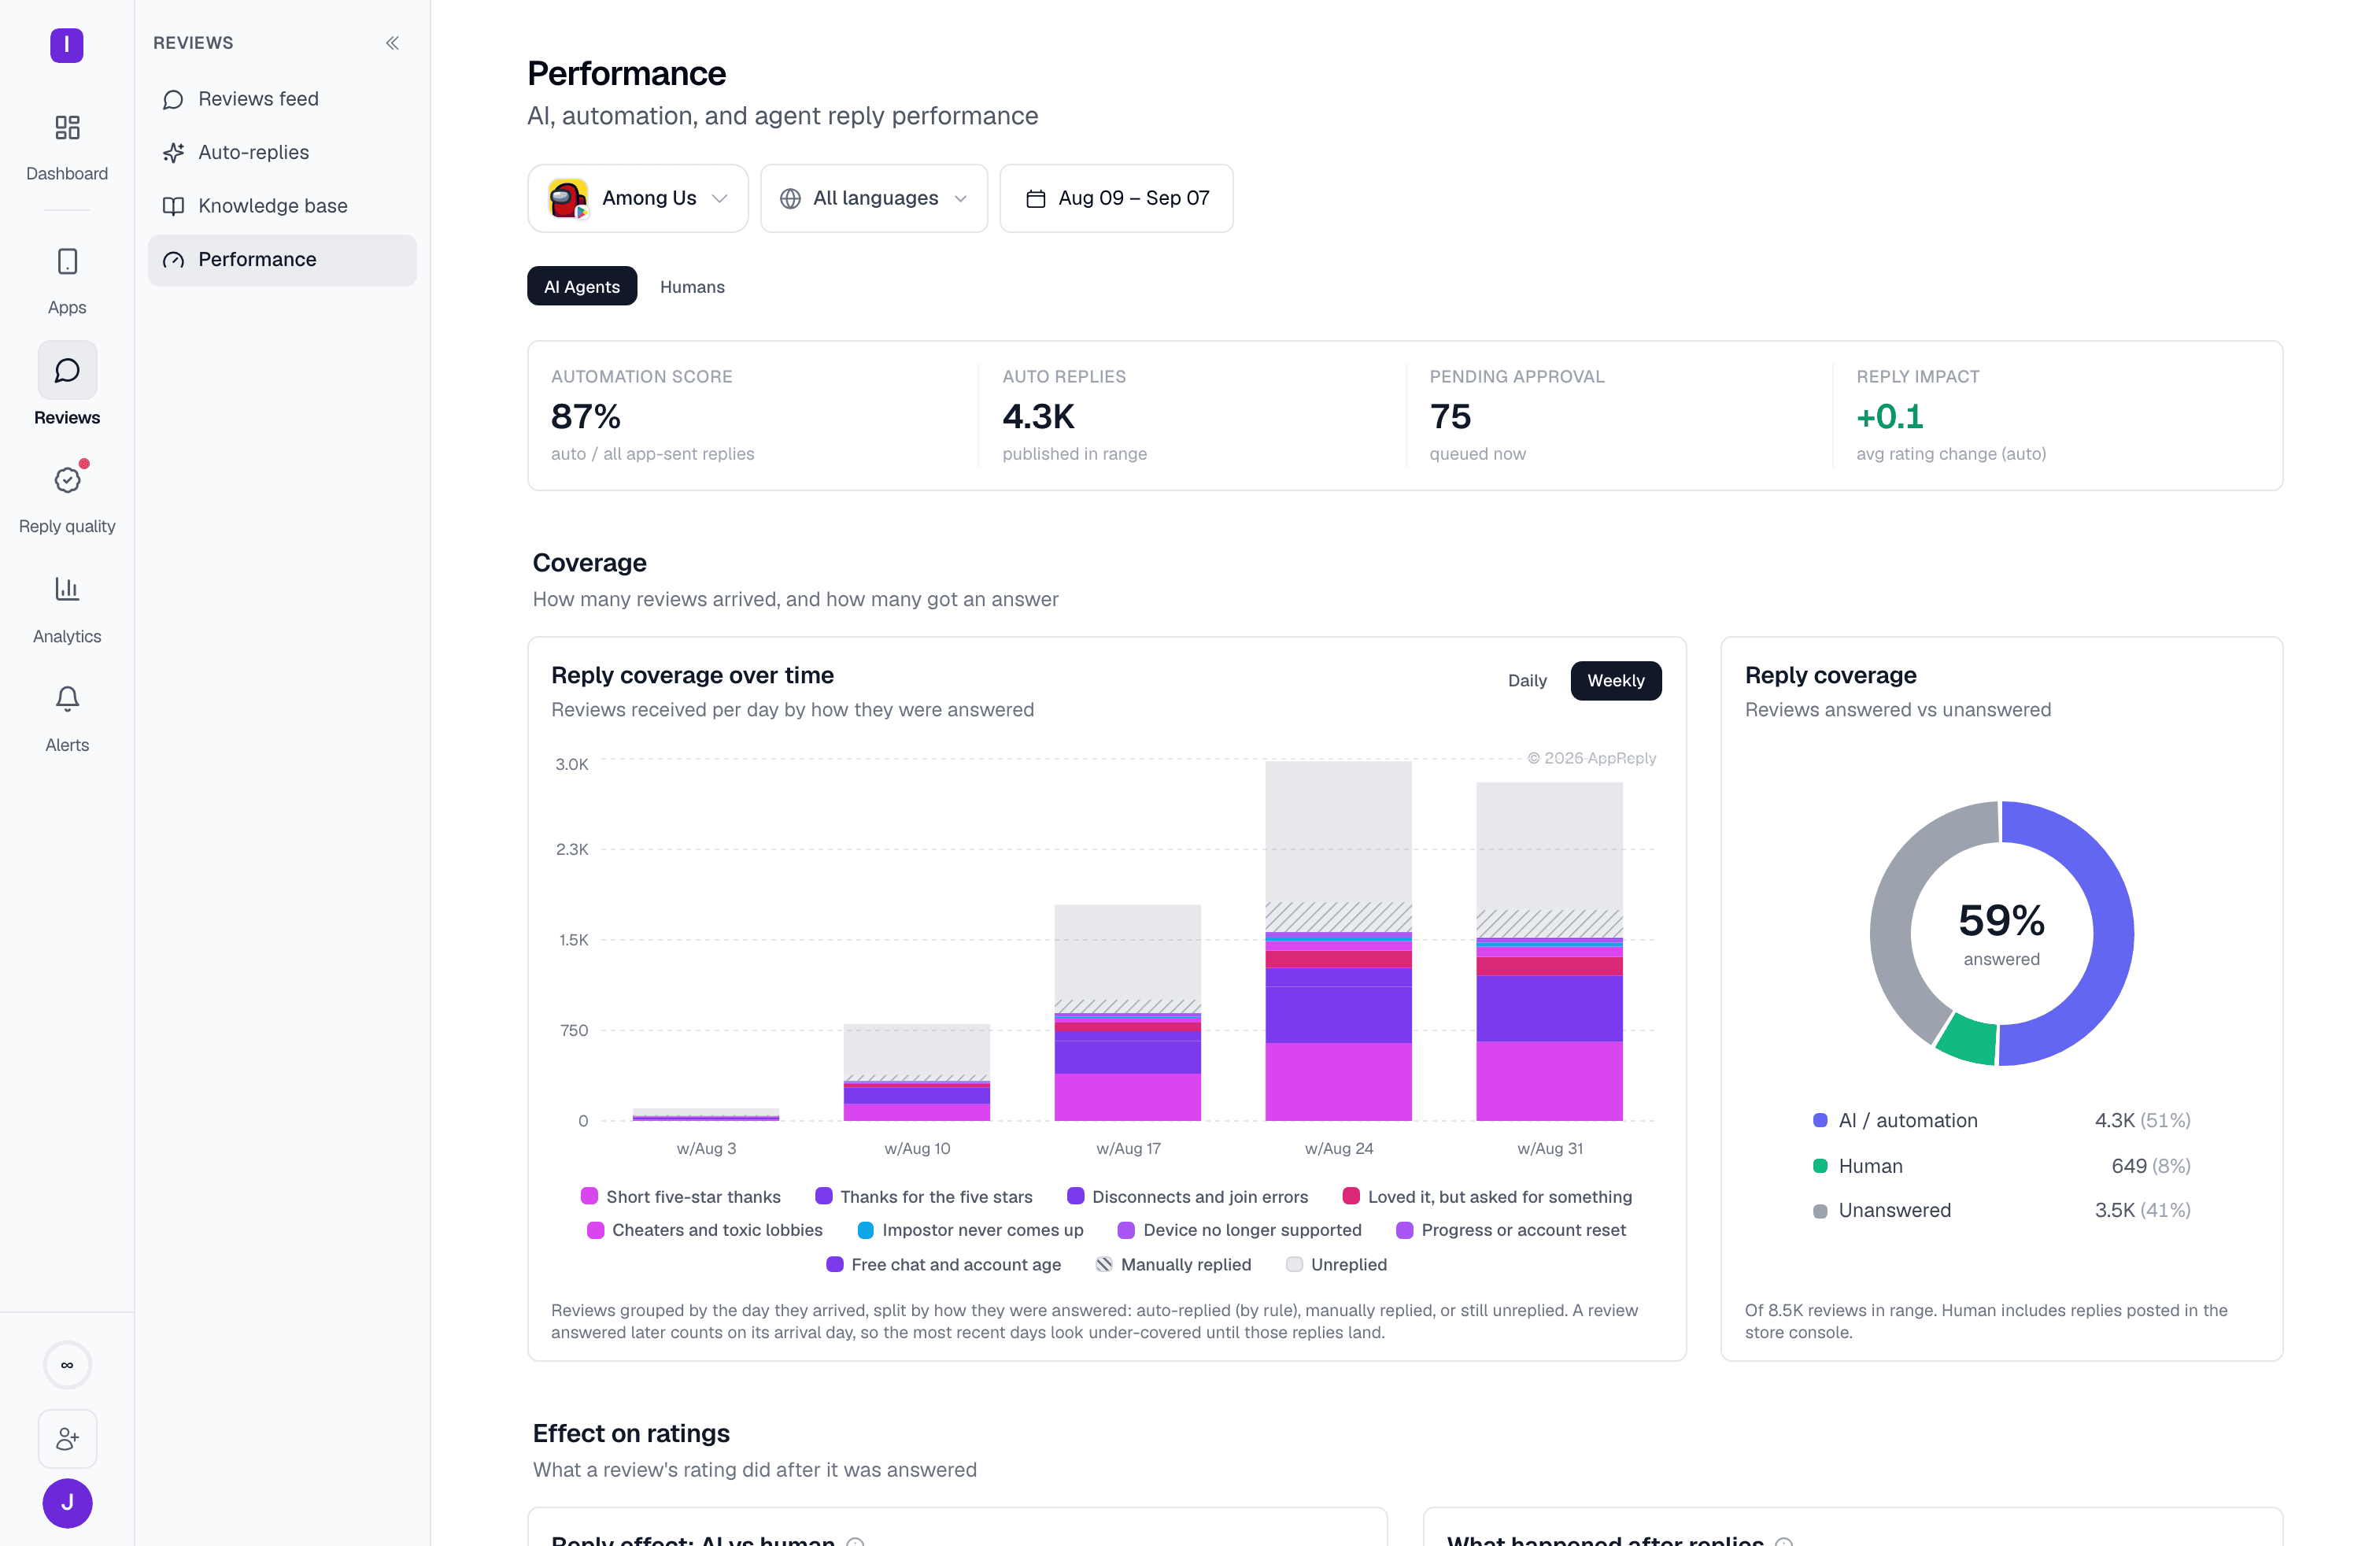
Effect on ratings
A table shows what a review’s rating did after it was answered, split by AI/Automation, Human, and Combined reply source. Each row shows replies published, how many reviews moved rating, the average rating change, and a win rate (the share of moved reviews that went up). A second card breaks every reply down by outcome — whether the rating rose, fell, or stayed the same — as a share of that source’s replies. Immovable 5★ reviews (5★ before and after) are counted here but can’t meaningfully move a rating.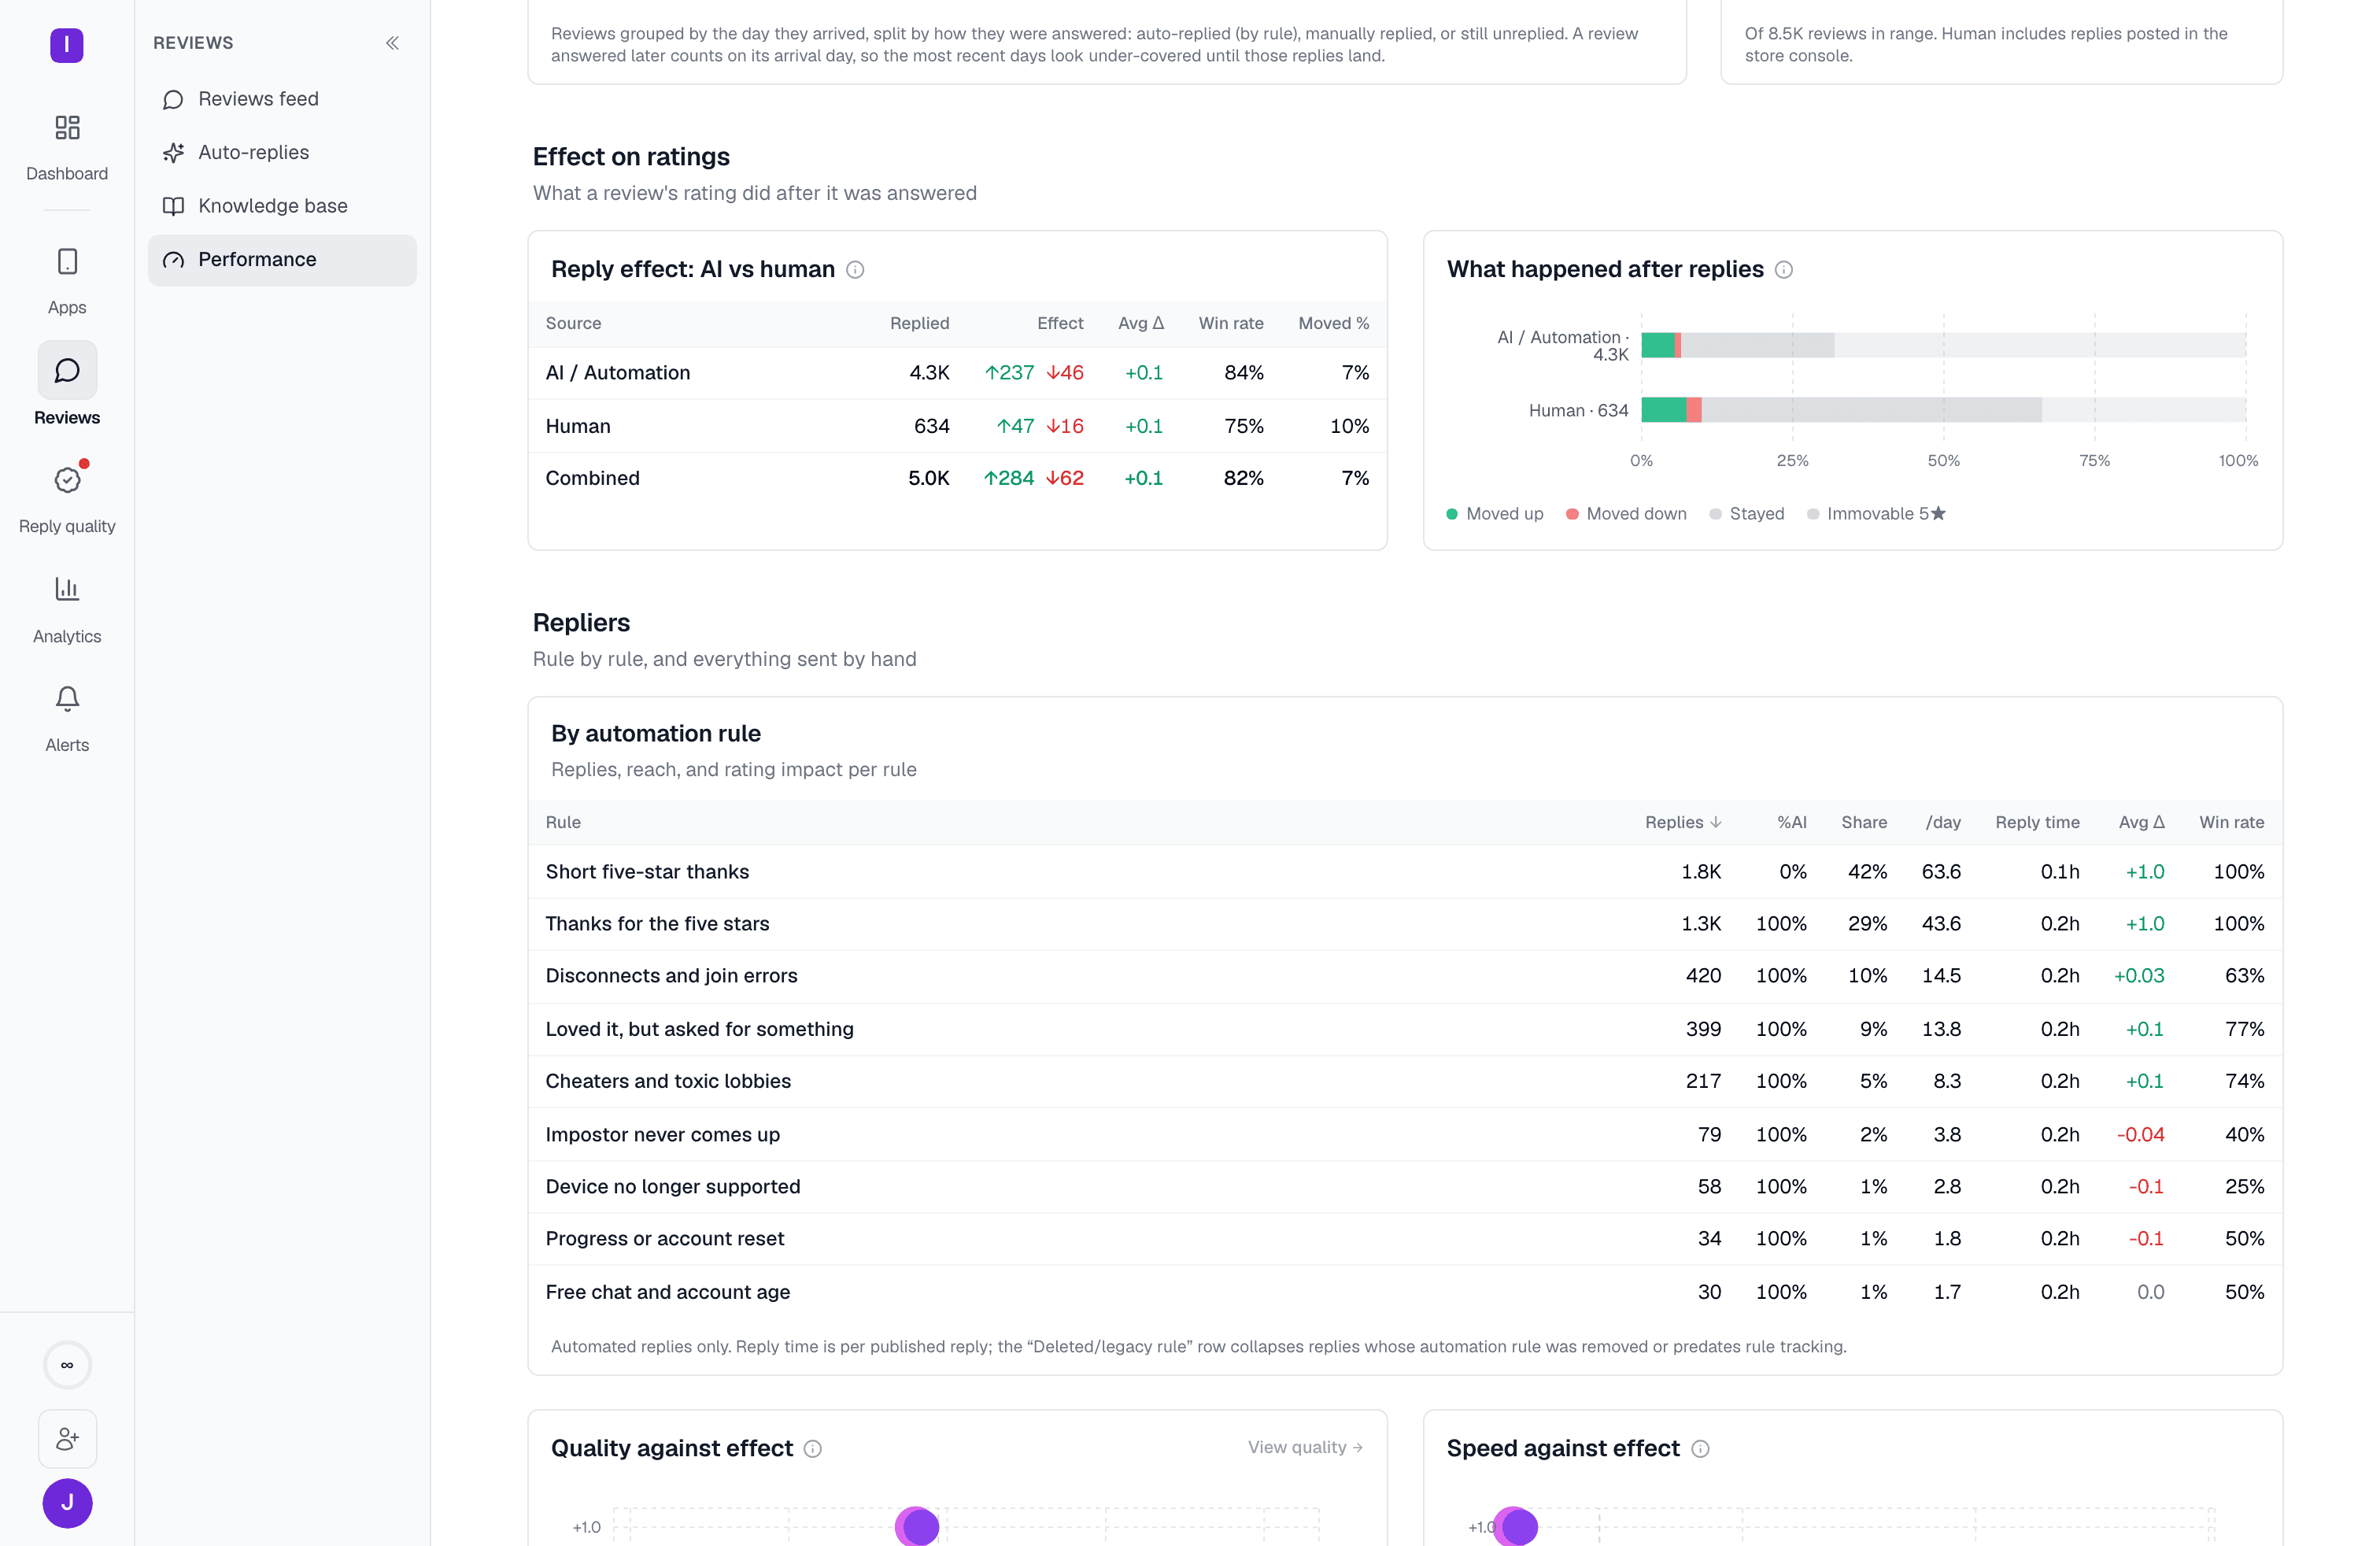
Repliers: by rule, by quality, and by speed
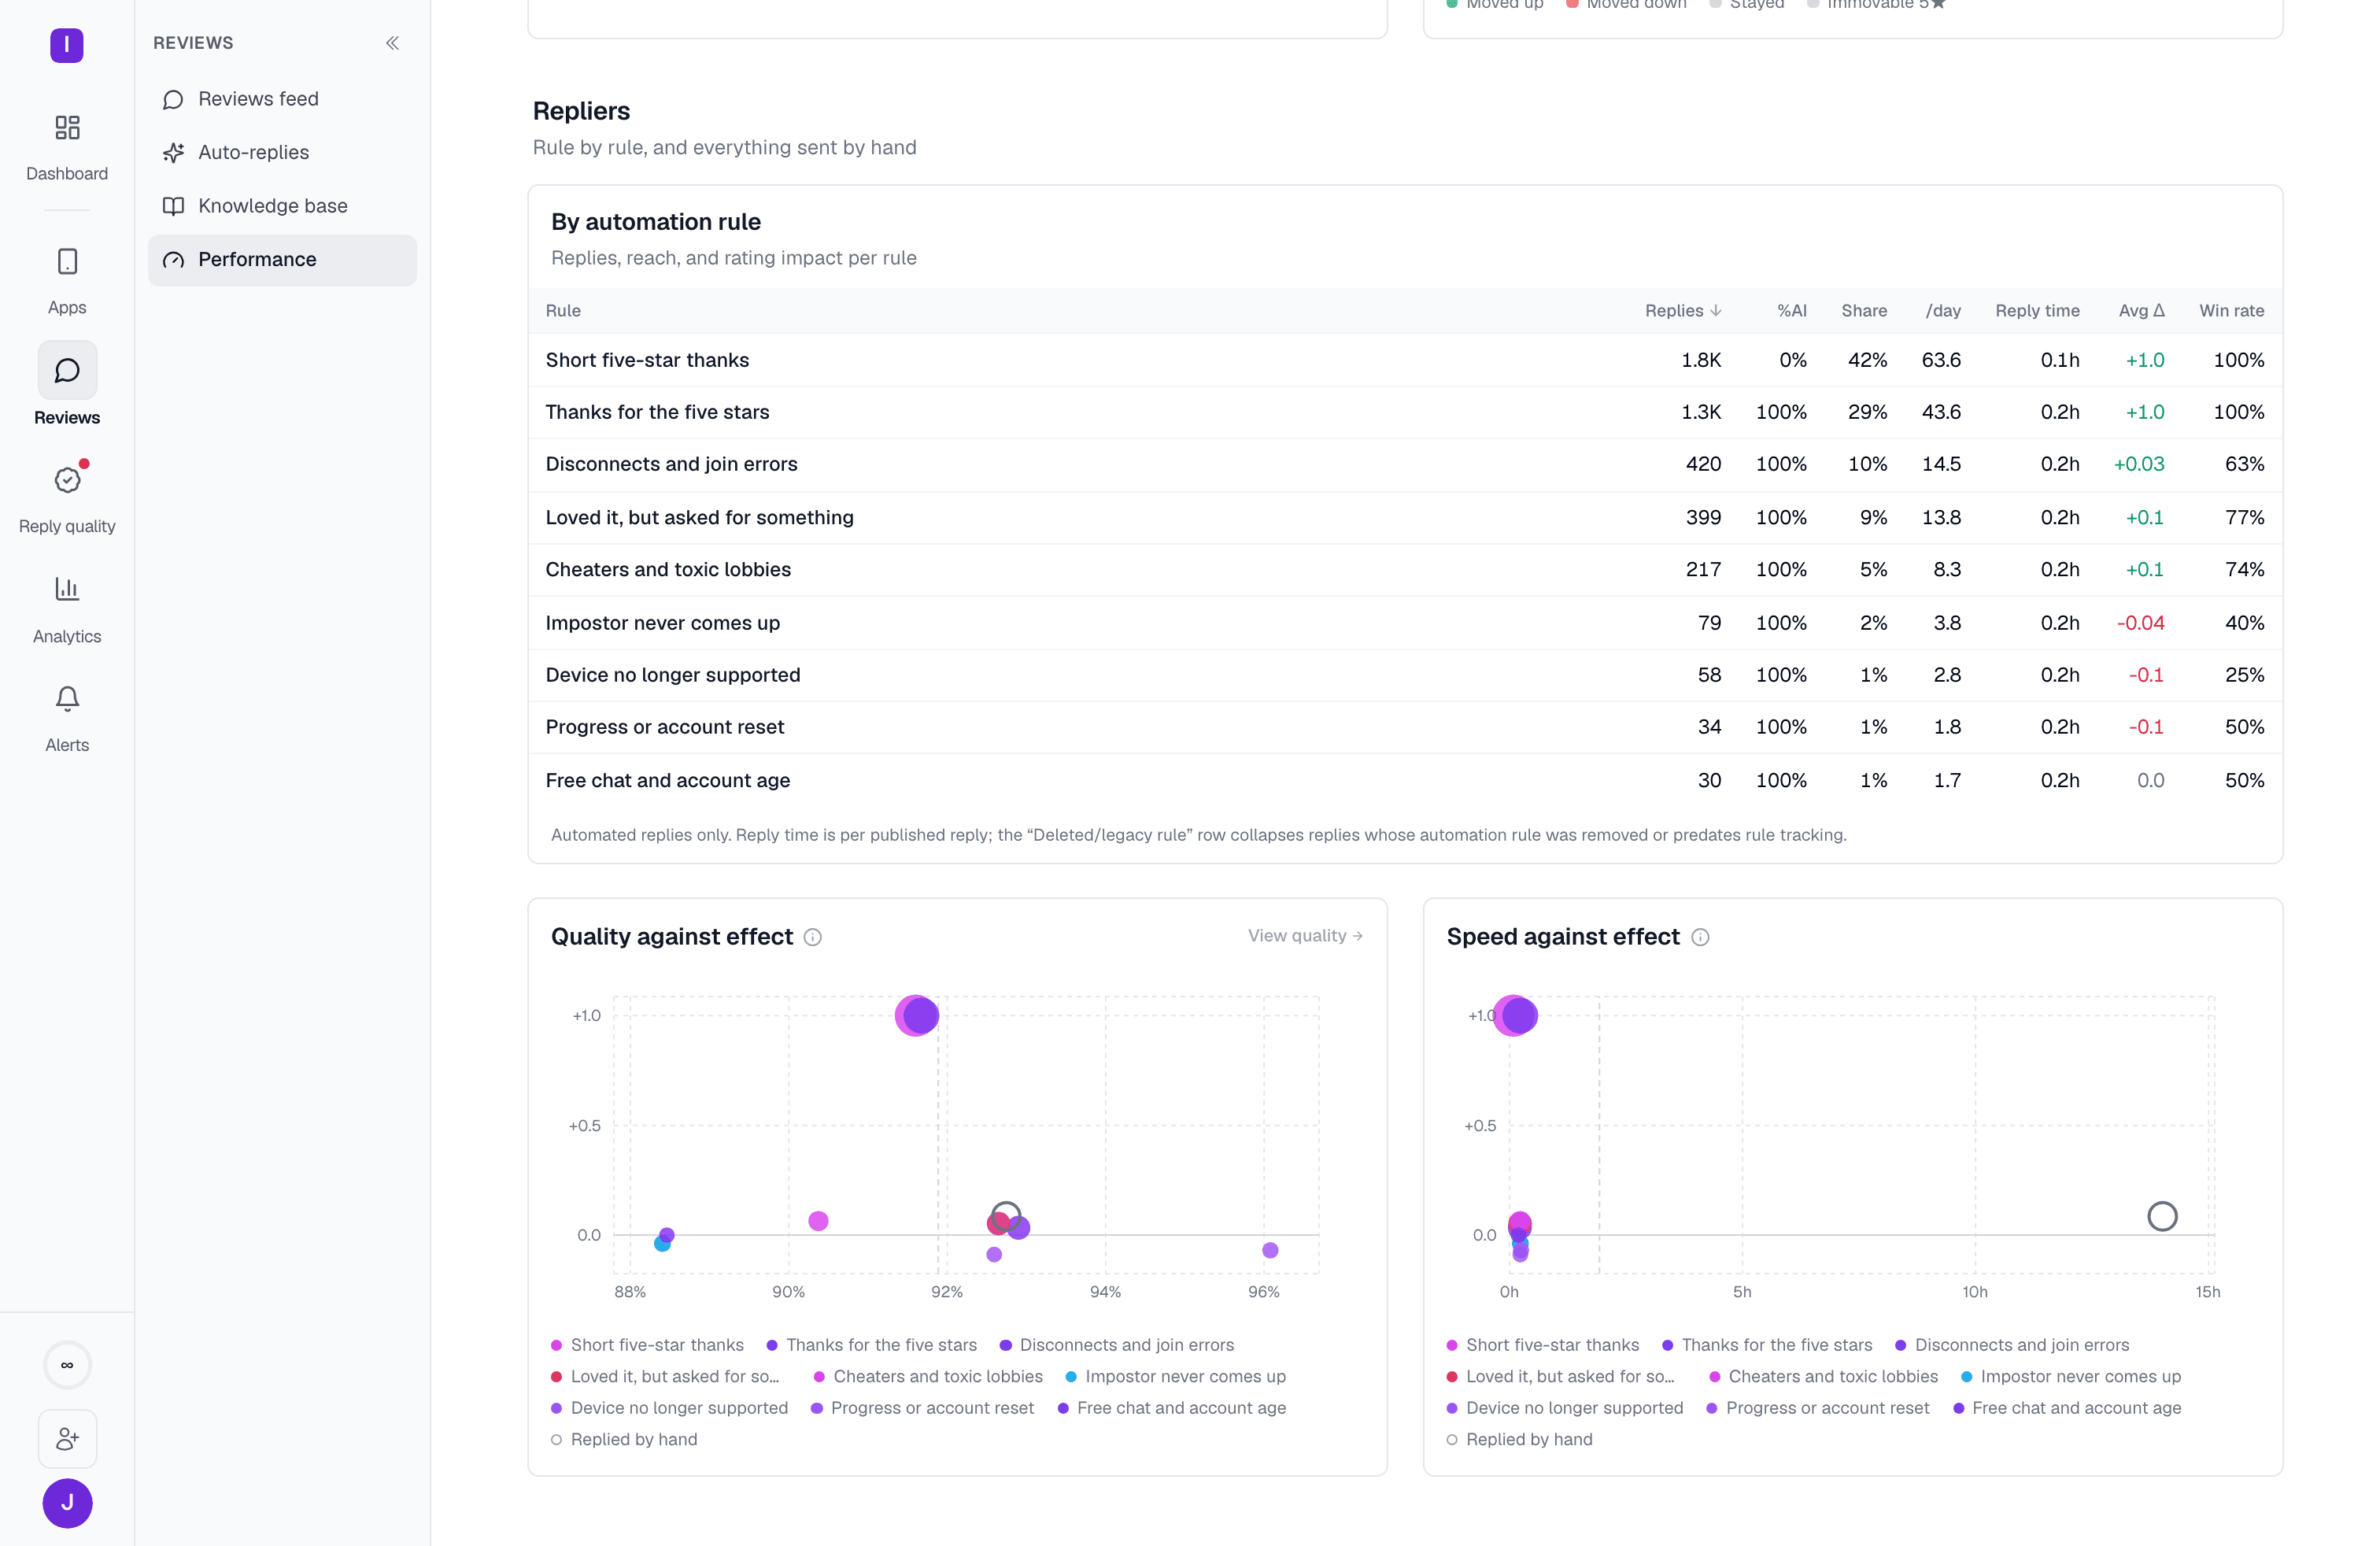
An Automation-by-rule table lists every automation rule that sent replies in the window, so you can see which specific rules are actually moving ratings, not just which are running most often:
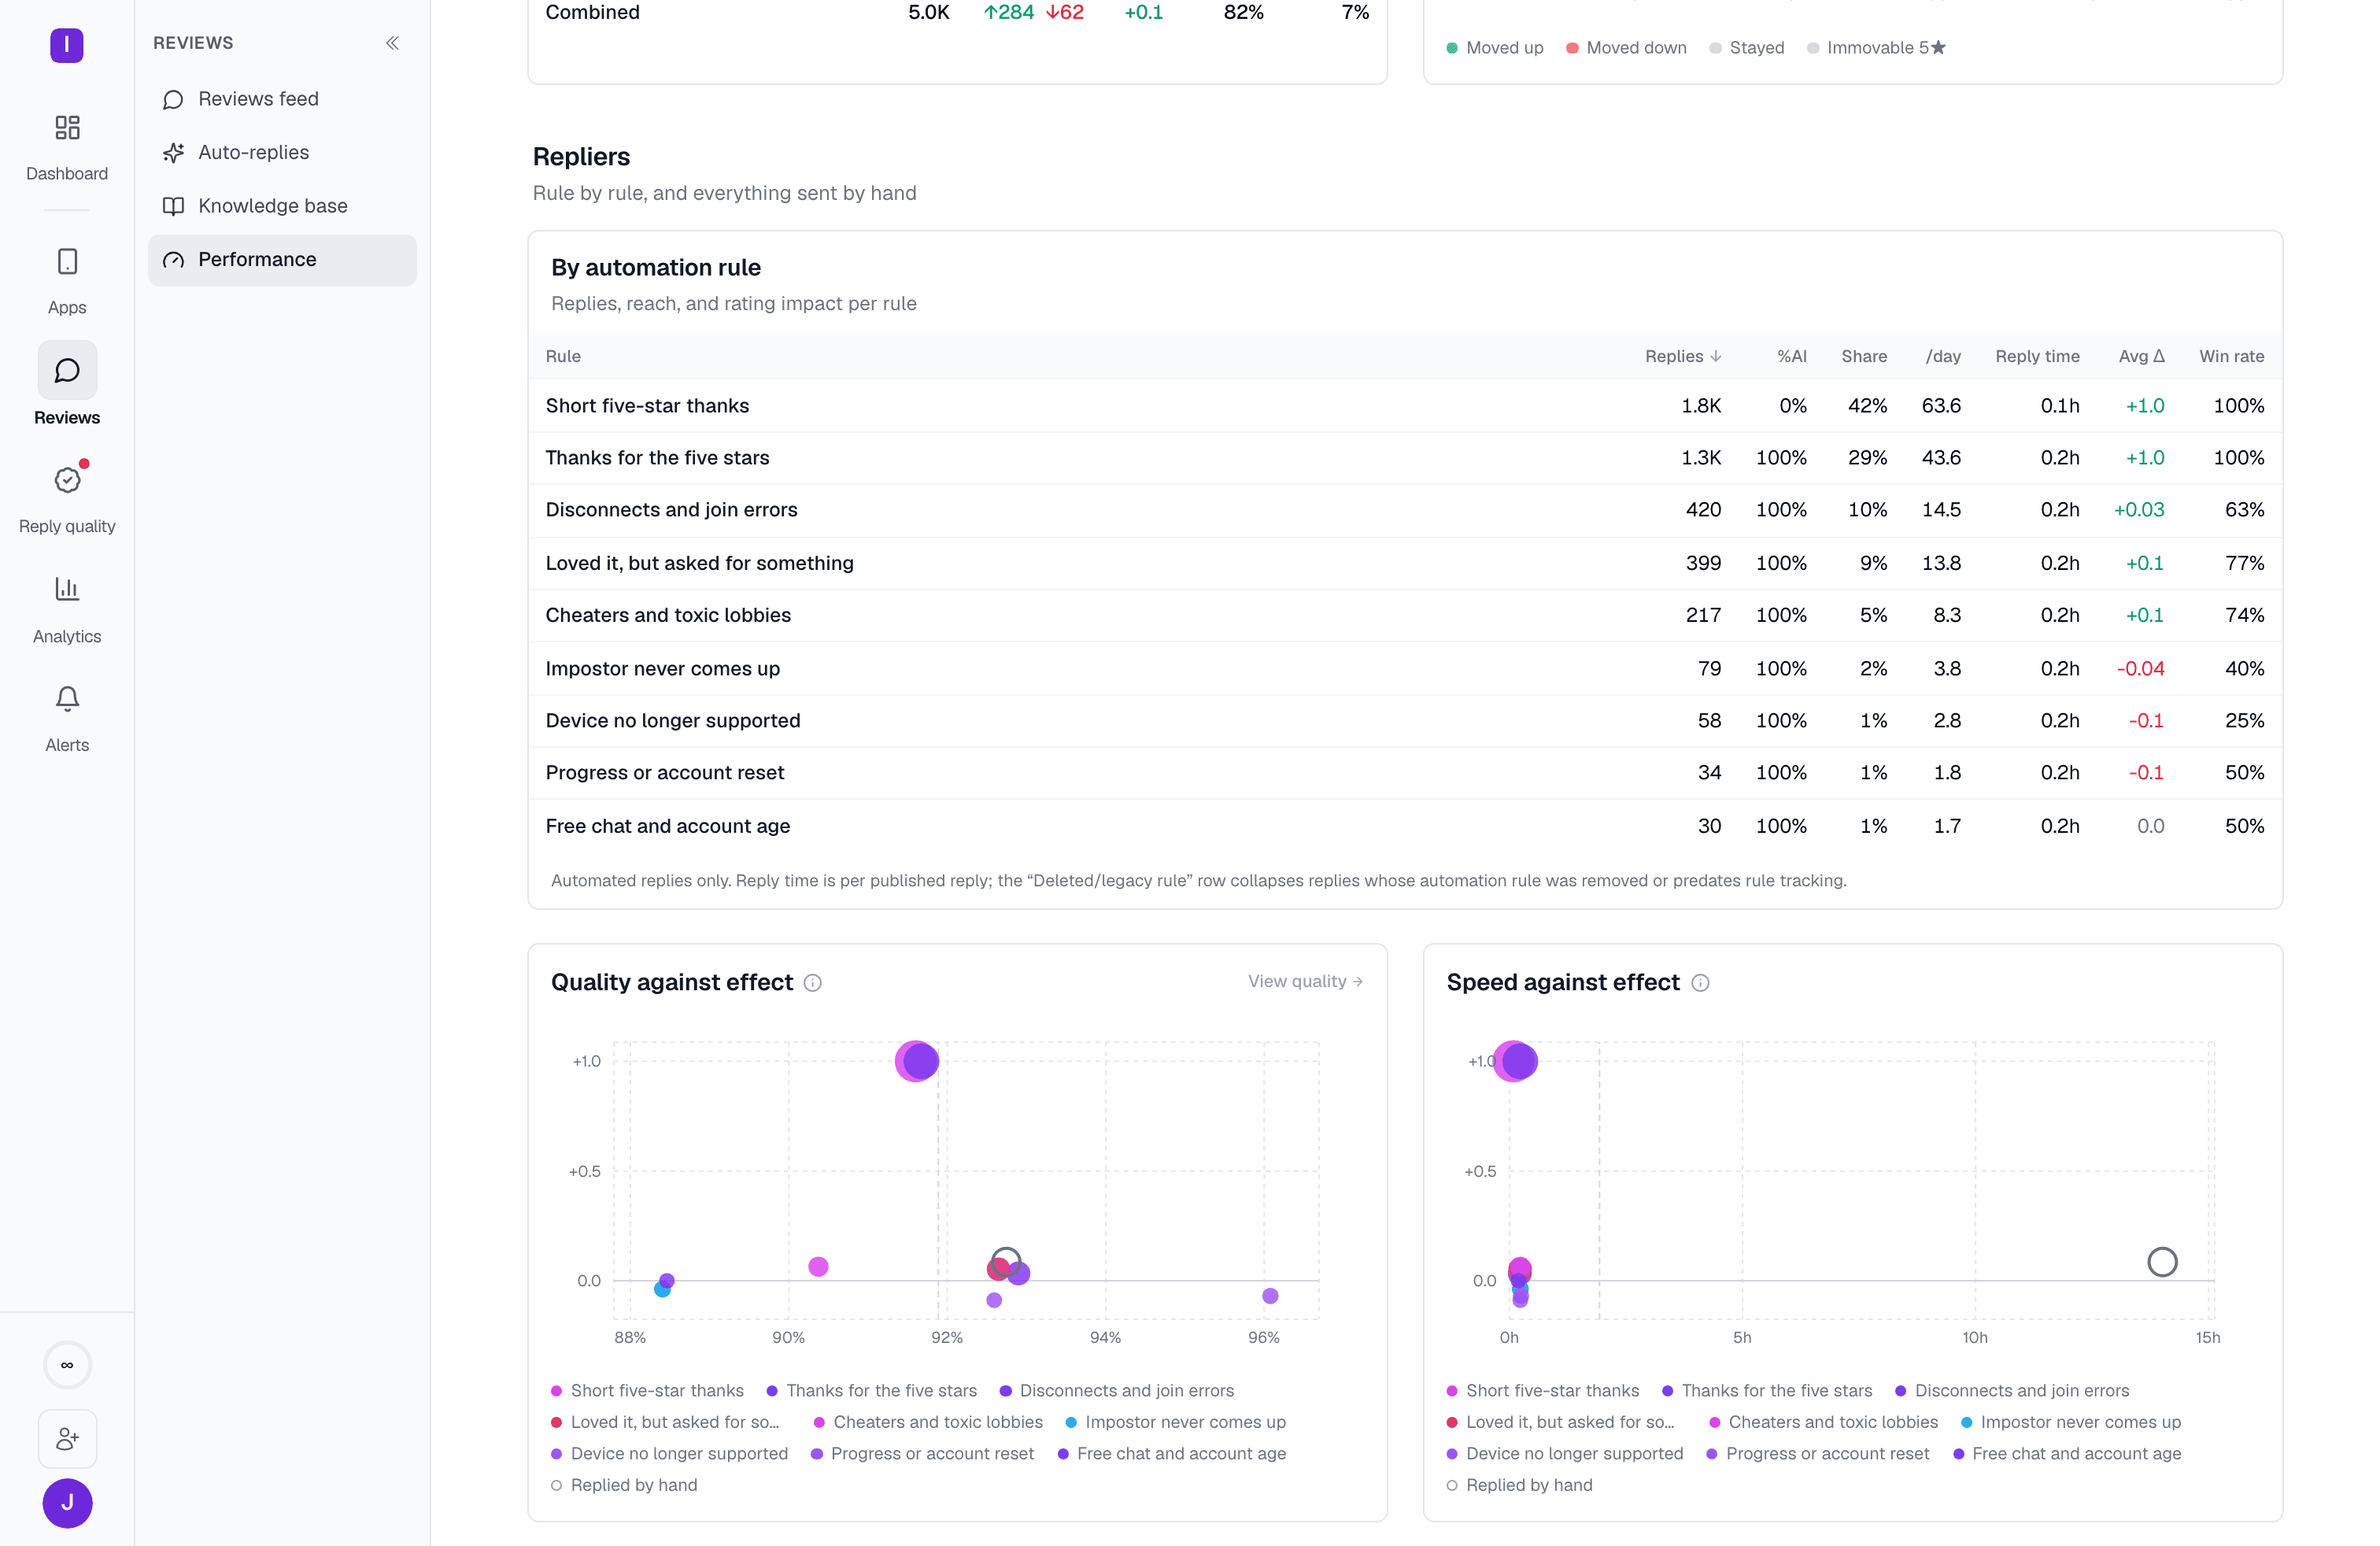
Below the table, two scatter charts plot every rule (and your hand-written replies, shown hollow) against the same rating-change axis:
- Quality against effect — each replier placed by how often its replies pass your reply-quality scorecard (left to right) against the rating change that followed (bottom to top). Dot size scales with replies sent; a dashed line marks the account’s own overall pass rate.
- Speed against effect: the same layout, placed by mean time to reply instead of pass rate. A dashed line marks the account’s own average reply time, drawn only once every replier’s time is known. Its legend is capped at ten rules with the same +N more rules toggle.
Humans tab
The Humans tab (labeled “Humans” next to “AI Agents”) swaps the automation-rule view for a per-person one: who on your team is replying, how fast, and what happens to ratings afterward.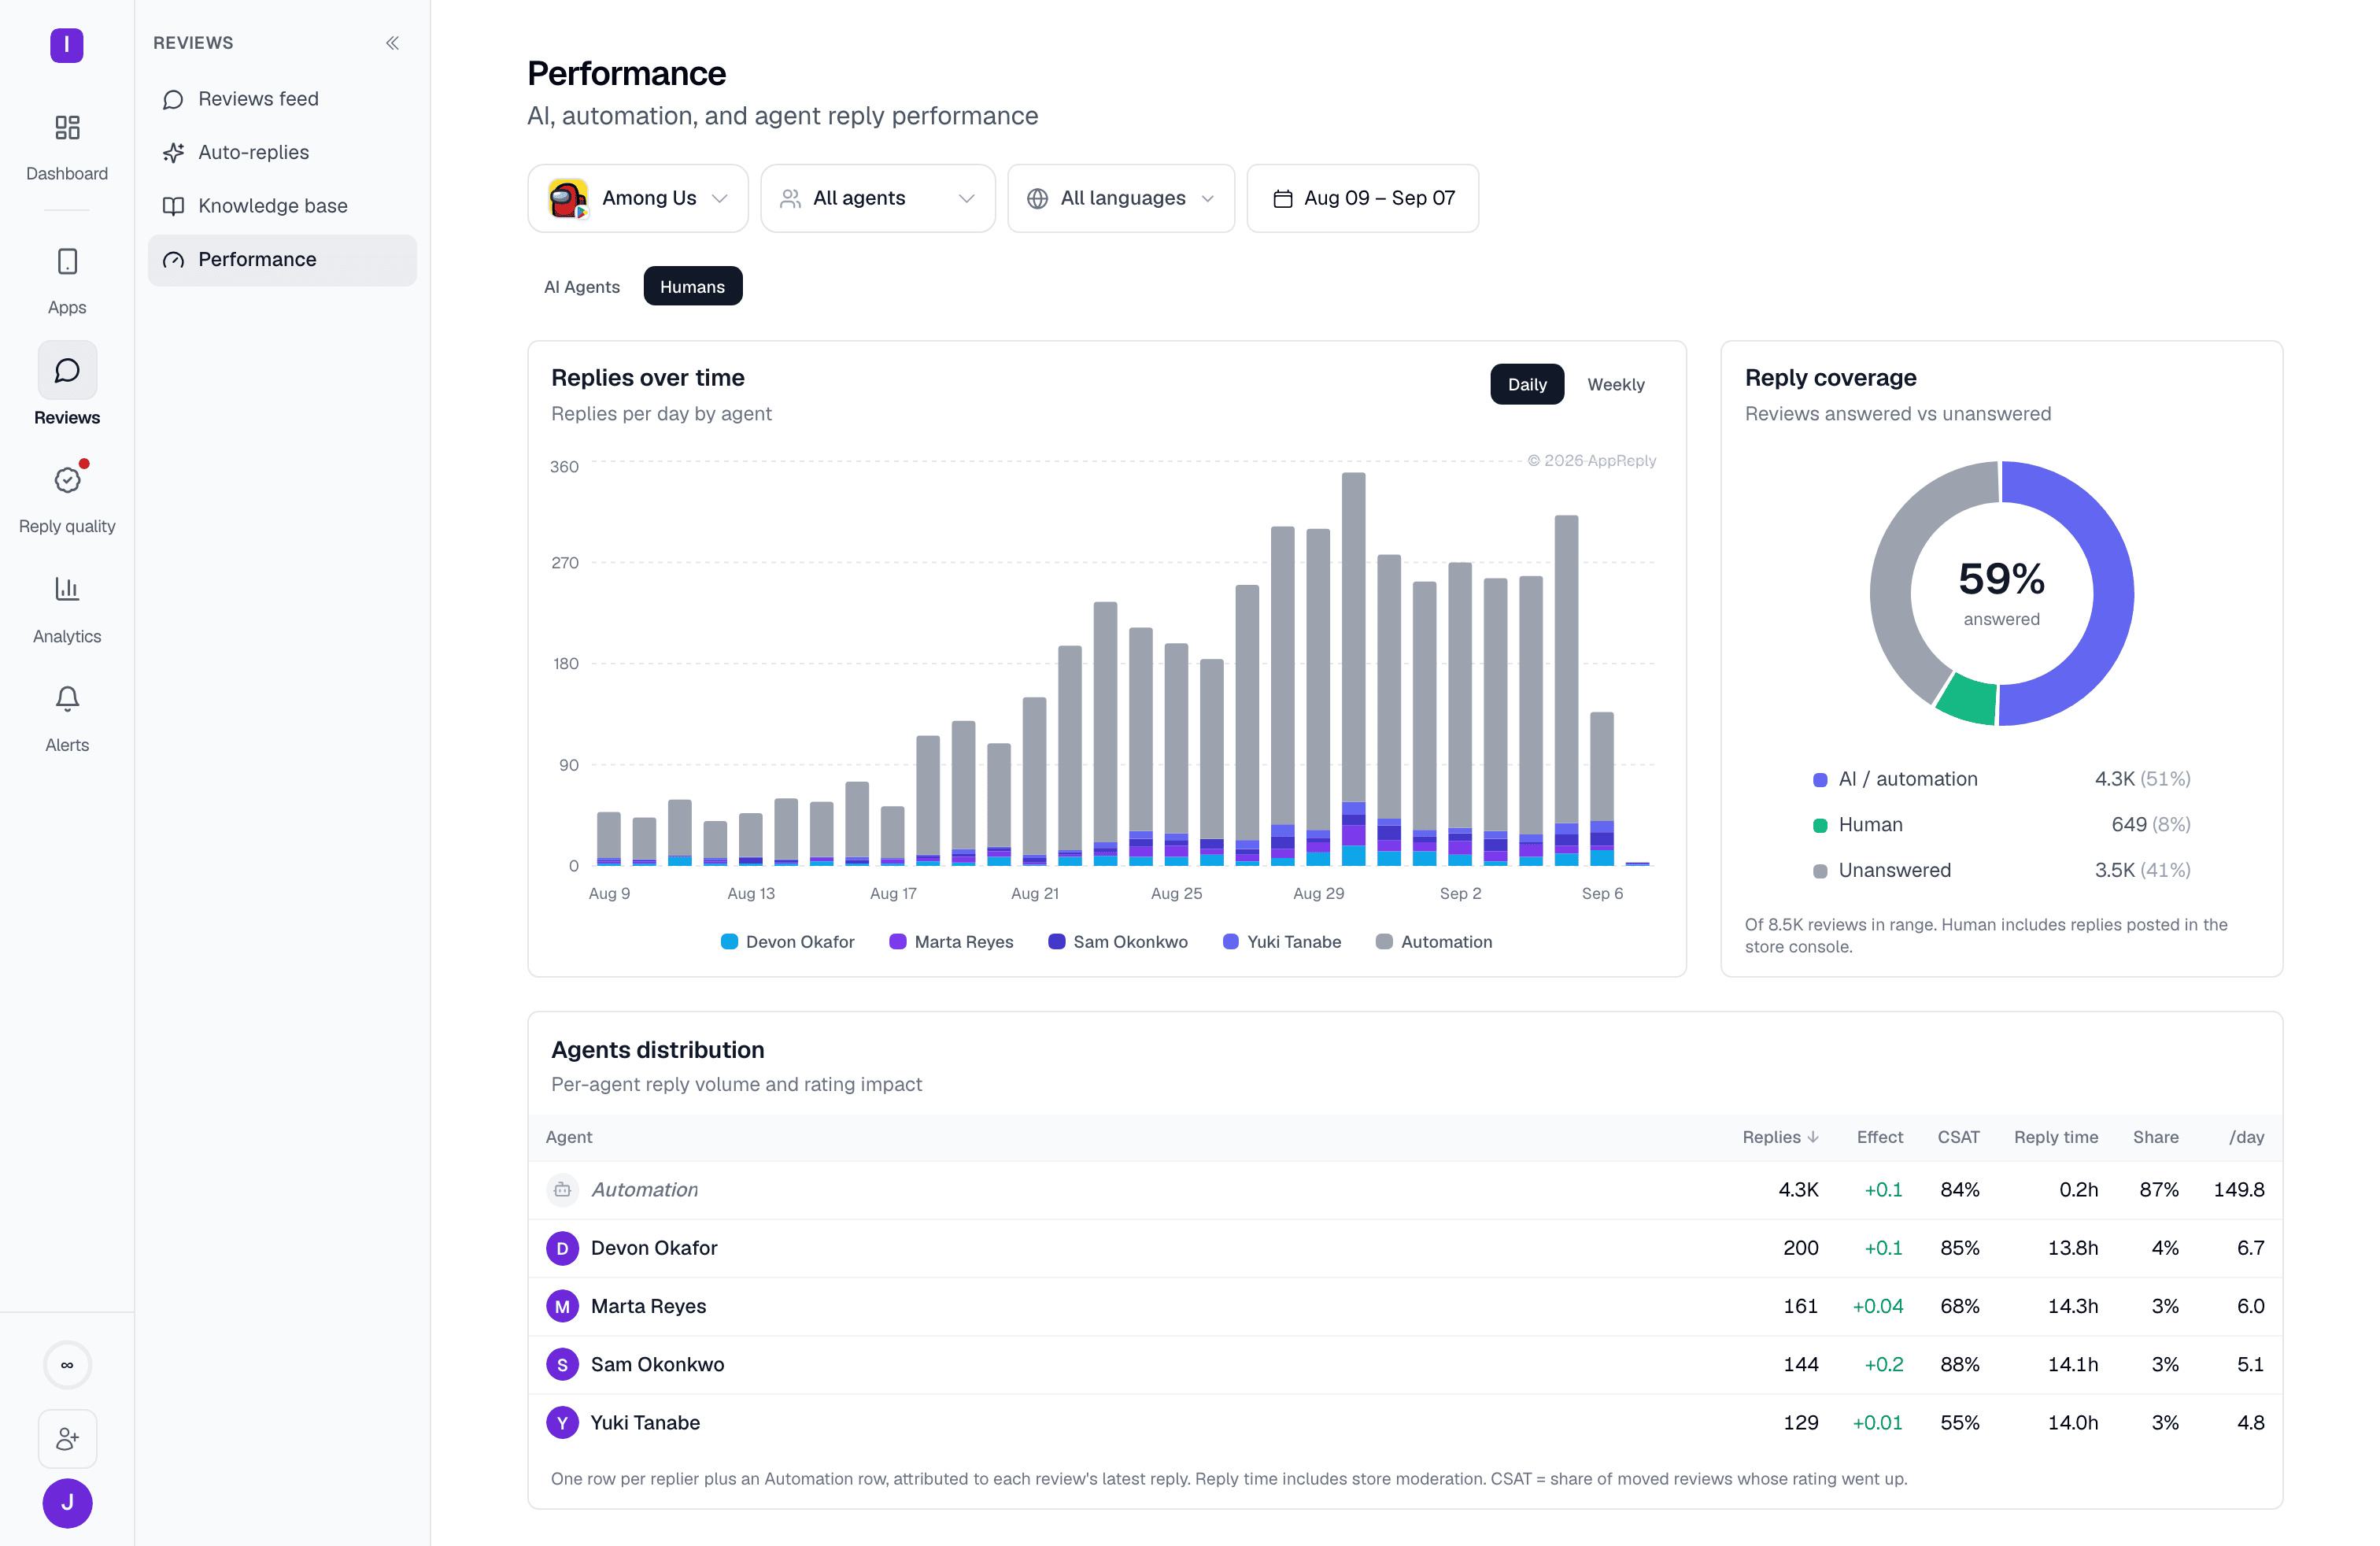
An agent selector in the filter bar (visible only on this tab) lets you narrow the chart and leaderboard to specific teammates.
Overview
How the shared filter bar and plan gating work across all of Analytics
Ratings
See the store rating trends these reply numbers are meant to move